
Microsoft said recovery was progressing across Microsoft 365 after a global disruption centered on Exchange Online blocked or delayed email, interfered with Outlook mailbox access and impaired calendar and scheduling functions. The outage, which began on November 12 and continued into November 13, reached far beyond a faulty inbox: organizations that use Microsoft’s cloud email as part of their daily communications had to work around missing messages and unreliable scheduling.
By late morning on November 13, Microsoft said it had completed recovery actions in parts of the affected Asia-Pacific infrastructure and was gradually restoring traffic elsewhere, according to The Guardian’s coverage of the incident. The company also cautioned that some customers could still see intermittent problems and that service capacity remained below its normal baseline. That leaves the practical status of the event unresolved even as the most acute disruption appeared to be easing.
Outlook and Exchange Online were the main points of failure
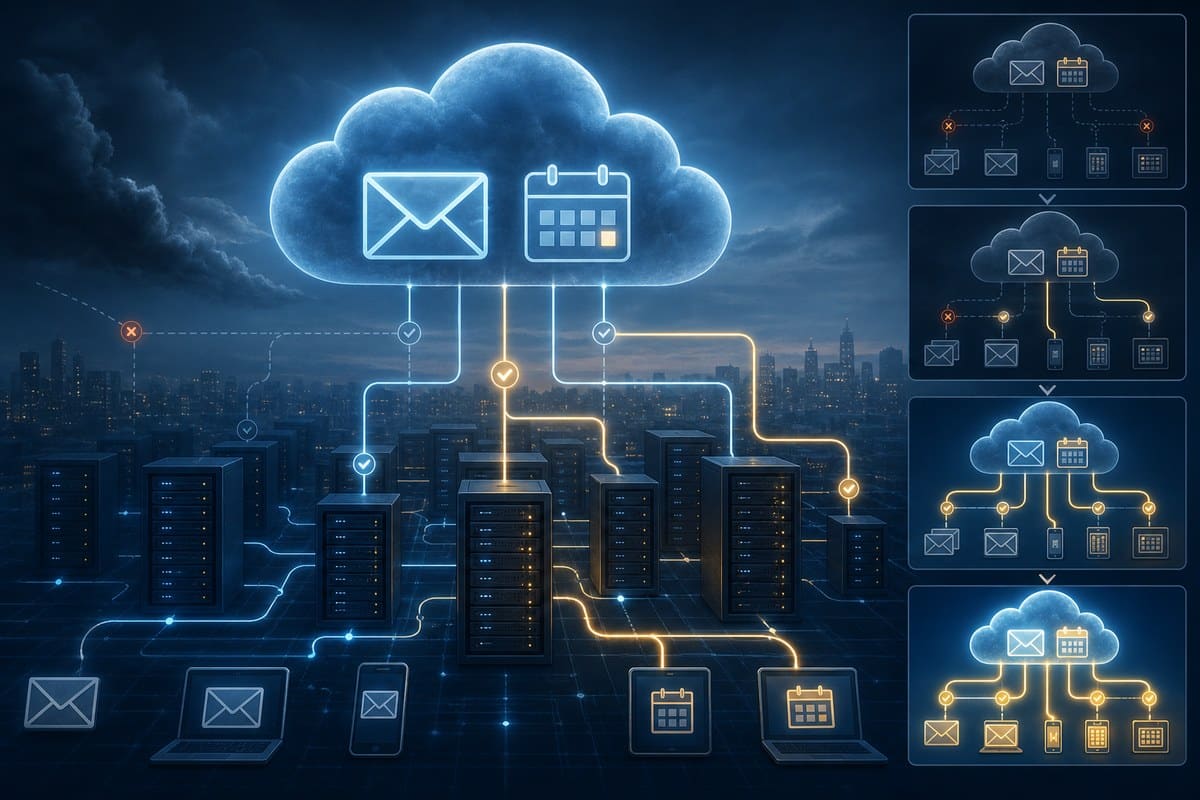
Reports consistently identified Exchange Online, Microsoft’s hosted business-email platform, and Outlook access as the most affected services. Customers reported trouble opening mailboxes, sending or receiving messages, and seeing new email arrive. Downdetector recorded more than 130,000 Outlook problem reports at its reported peak, a useful signal of the outage’s visibility but not a count of affected people, accounts or businesses.
Microsoft 365 encompasses a collection of services, so a broad outage label can obscure important differences. Teams was affected, but the evidence does not support describing the entire collaboration service as offline. India Today’s account of Microsoft’s updates indicated that core Teams calls, meetings and messaging largely continued, while features dependent on Exchange Online—particularly calendars, meeting scheduling and some chat-creation functions—were disrupted.
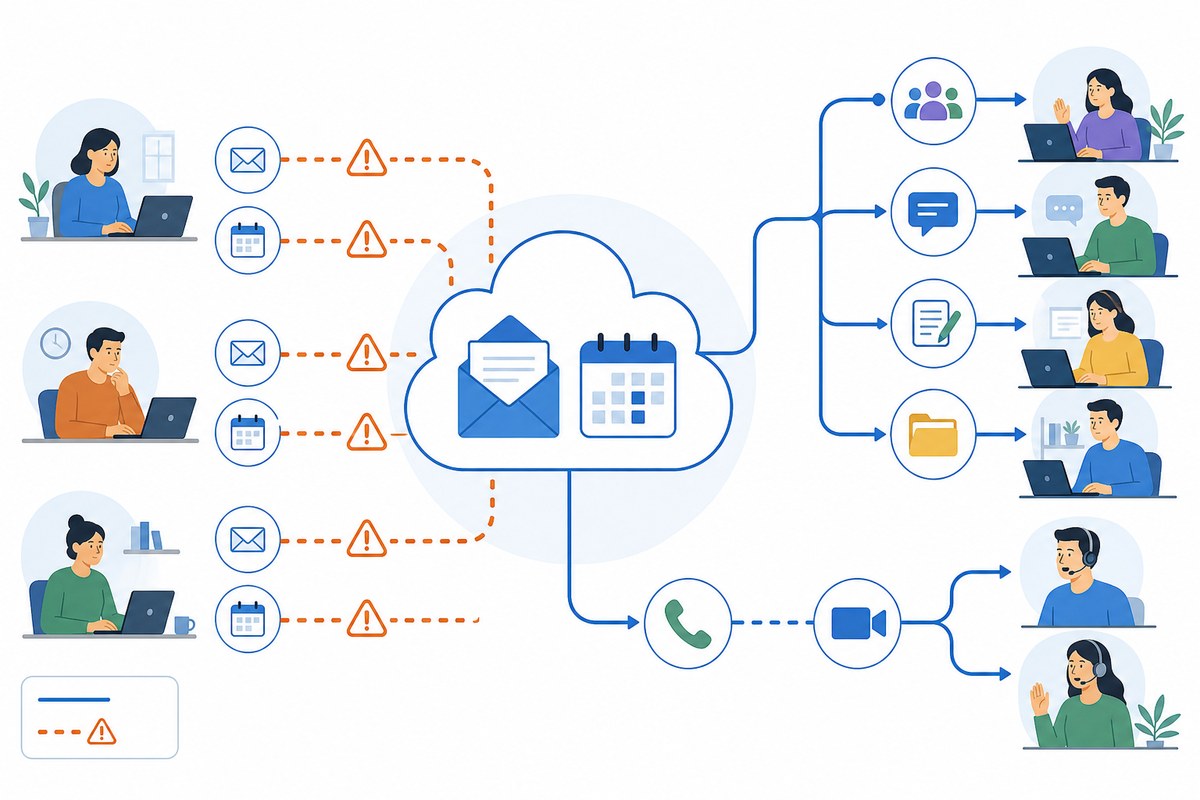
That feature-level distinction explains why a calendar failure can look like a Teams failure to a user. A meeting invitation, room booking or availability check may rely on mailbox and calendar data even when the app’s voice and video systems remain available. It also illustrates the operational fragility created when email, calendars and collaboration software are presented as one suite but run through interdependent cloud services.
Recovery work focused on traffic, delayed mail and capacity
Microsoft’s mitigation involved restoring traffic gradually and processing backlogs of delayed messages. The company extended its email timeout window to 48 hours while it worked through delayed-mail queues, according to reports citing its service updates. The move was intended to keep messages in the delivery process longer as systems recovered; it was not a declaration that normal delivery had already resumed.
Specialist publication CX Today reported that Microsoft logged the Exchange Online incident, identified as EX1550543, at 16:17 UTC on November 12. The company opened a broader Microsoft 365 incident at 18:26 UTC. By 07:25 UTC the next day, Microsoft had reported positive server-stability results after a patch involving authentication and routing configuration, and it reported early signs of stabilization at 09:03 UTC.
Those timestamps also help reconcile competing estimates of the outage’s duration. News reports described disruption lasting more than 12 hours, about 15 hours, or more than 18 hours, depending on when they measured from and whether they counted the continuing period of degraded service. Microsoft had not published a final post-incident analysis or a definitive end time in the cited reporting, so no single duration should yet be treated as conclusive.
Cause remains under investigation
Microsoft said it had no indication of malicious activity, but that is not the same as a completed explanation of what went wrong. Its preliminary investigation, as reported by India Today and CX Today, pointed to a process used to establish secure connections becoming overwhelmed on affected servers. Microsoft was also reverting a recent network configuration change that coincided with the beginning of the impact to determine whether it played a role.
Both details are preliminary. An overloaded connection-establishment process describes an observed failure mechanism; it does not settle why the load or behavior arose in the first place. Likewise, rolling back a configuration is a sensible containment action during a live incident, not proof that the configuration caused the event. Microsoft had not, in the available reporting, issued a final root-cause finding.
The outage’s breadth was visible outside Microsoft’s own applications. OpenAI said new Microsoft connector connections could fail and related tools might not work as expected, while Anthropic reported an upstream-provider issue affecting its Microsoft 365 connector. Those reports, also documented by The Guardian, show how disruptions in a major workplace platform can surface in adjacent software without making every affected product a separate outage.
Public bodies moved to contingency communications
For organizations that cannot simply wait for an inbox to return, the incident had immediate operational consequences. Hospitals and public bodies in several countries reported communication disruption or activated backup procedures. In western England, some NHS organizations advised patients to keep appointments unless told otherwise and to use telephone contact where possible, according to BBC reporting on the health-service response. Essential services continued at least at some of the affected organizations.
A separate Dynamics 365 Contact Center incident began at 17:00 UTC on November 12, according to CX Today. Microsoft treated it as a distinct incident, CR1550885, and later reported that agent access, voice and messaging had been restored after just under eight hours. Separating it from the Exchange Online event matters because both hit business communications at roughly the same time, but they were not presented as one confirmed technical failure.
Microsoft’s latest public position was therefore more limited than a full all-clear: mailbox access and delayed-email processing were improving, recovery actions were being extended across affected infrastructure, and capacity had not fully returned to normal. Intermittent issues remained possible, and the company had not yet published a final root-cause analysis.